
When you ask a language model to retrieve «the most similar thing» to a question, it does not open a normal database and search word by word. It does something stranger: it turns every text into a list of hundreds of numbers and compares numerical distances. That list is called an embedding, and the mechanism that stores and searches it is a vector index.
Texts become points in space
An embedding is the result of passing text through a neural-network model (for example the BERT family or general-purpose embedding models) that returns a vector of floating-point numbers — typically 384, 768 or 1536 dimensions. The idea is that texts with similar meaning land close together in that mathematical space, even if they share no single word. «Dog» and «pet» end up a few distance units apart; «dog» and «corporate tax» are very far away.
Measuring «similarity» is a geometric operation
Once you have two vectors, deciding whether they are similar is just computing a distance. The three most common metrics are cosine similarity (the angle between the vectors’ directions, normalized by magnitude), the dot product (fast but sensitive to the magnitude of the vectors) and Euclidean distance (the actual length of the line joining them). None is «the right one»: choosing between them changes the results, which is why indexes are configured per application.
Searching one by one is too slow
The naive approach would compare the query against every one of the millions of stored vectors. That is called exact k-NN and it works, but the cost grows linearly: with a hundred million documents and 768 dimensions, each search requires tens of billions of floating-point operations. In practice nobody does that. Real systems use approximate nearest neighbor (ANN) search, which trades a tiny fraction of precision to bring query time down from seconds to milliseconds.
HNSW: the graph that jumps between points
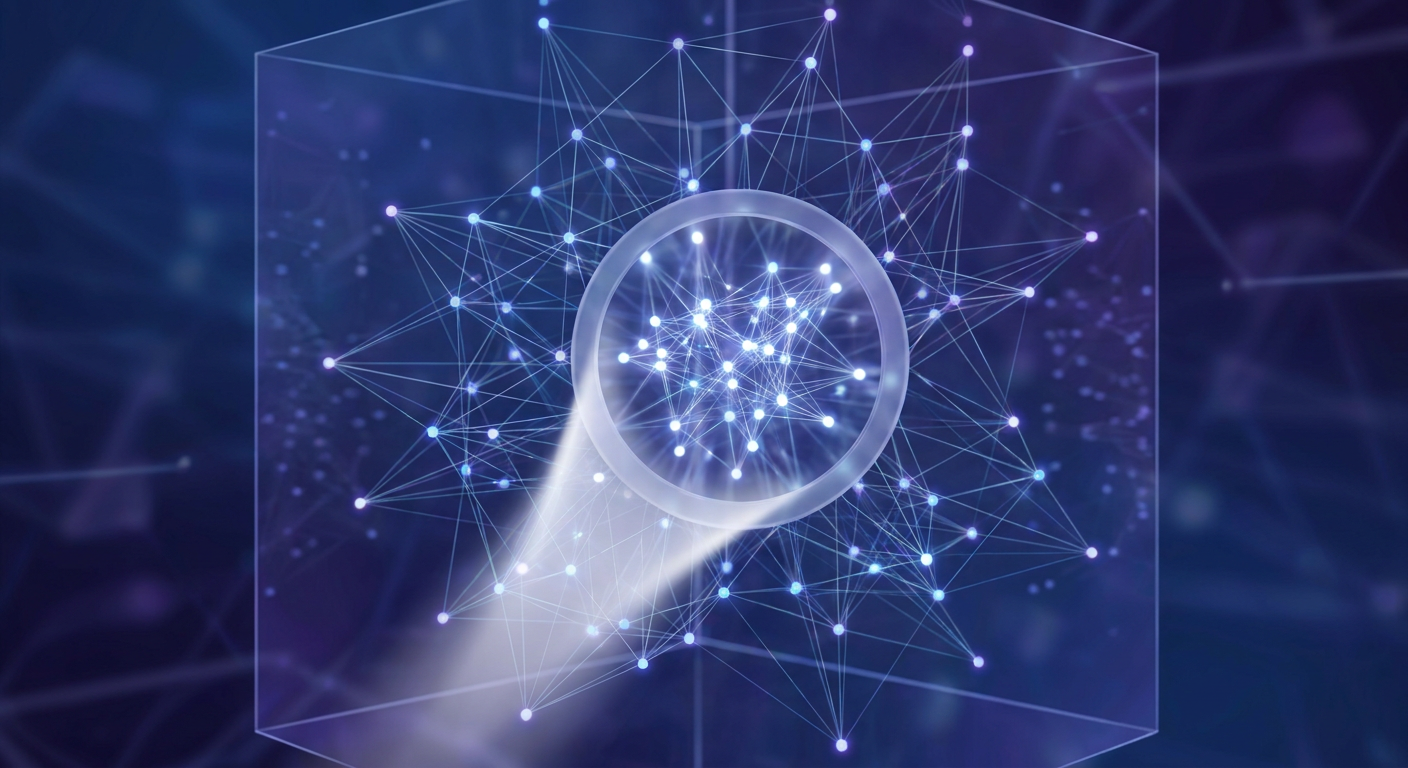
One of the most widespread ANN algorithms is HNSW (Hierarchical Navigable Small World). Instead of scanning every vector, it builds a graph where each point connects to a few close neighbors. The key lies in its layers: in the upper layers the links are long and jump across the whole space; in the lower ones they get closer and closer to the exact point. Search starts at the top, jumps far, and descends through the layers, like driving on a highway and then down small streets to a neighborhood. The cost drops from O(N) to something near O(log N).
IVF-PQ: compressing to fit in memory
Another common trick is the inverted file with product quantization (IVF-PQ). First the vectors are partitioned with a clustering algorithm (k-means) into centroids: the query is now compared only against the most promising centroids, not everything. Then, instead of storing each 768-float vector (over 3 KB), it is split into subvectors and each chunk is approximated with a code table: you go from tens of megabytes to just a few per document. The trick is called quantization, and with it indexes fit in RAM even when the corpus has hundreds of millions of entries.
The balance of three numbers
Every vector index is described by three competing variables: recall (what fraction of the true neighbors it finds), throughput (how many queries per second it sustains) and memory (how much it occupies). Raising search quality increases recall but lowers queries per second; compressing with PQ saves memory but risks recall. Production systems measure this triangle with public benchmarks and tune their parameters (number of explored neighbors ef, number of centroids, quantization depth) until they find the point where quality is not noticeable in the result.
This is what makes «RAG» faster
If you have heard of RAG (retrieval augmented generation), this index is exactly the piece that pulls the relevant fragments before the model generates an answer. That is why conversational search engines, chatbots with corporate memory and embedding search tools depend on engines such as Faiss, Milvus, Qdrant or pgvector instead of a plain LIKE in SQL. «Similarity» is not written in a query: it is computed in the geometry of a thousand dimensions, and the vector index is the library that makes that geometry queried in milliseconds.