
Scaling a cache or a database to several servers seems easy: you split the keys across nodes and you are done. The problem arrives the day a node goes down, or you add a new one, and with the naive split almost every key changes owner at the same time. Serving a cache that has just frozen en masse is the worst thing that can happen to a service with traffic spikes. That is exactly what consistent hashing is for.
The problem: splitting without reshuffling the whole world
Imagine you have N cache servers and decide where each key lives with a classic arithmetic formula: bucket = hash(key) mod N. The modulo operation returns the remainder of a division; with it, every key always lands on the same node as long as N does not change.
But the day a node shuts down (N drops to 5) or you add one (N becomes 7), the divisor changes and so do the remainders of almost every division: the vast majority of keys jump to another node. For a cache that means generalized cache misses all at once, and every client hitting the backend in what is known as a thundering herd: precisely the load spike you were trying to avoid.
The idea: a ring instead of an arithmetic formula
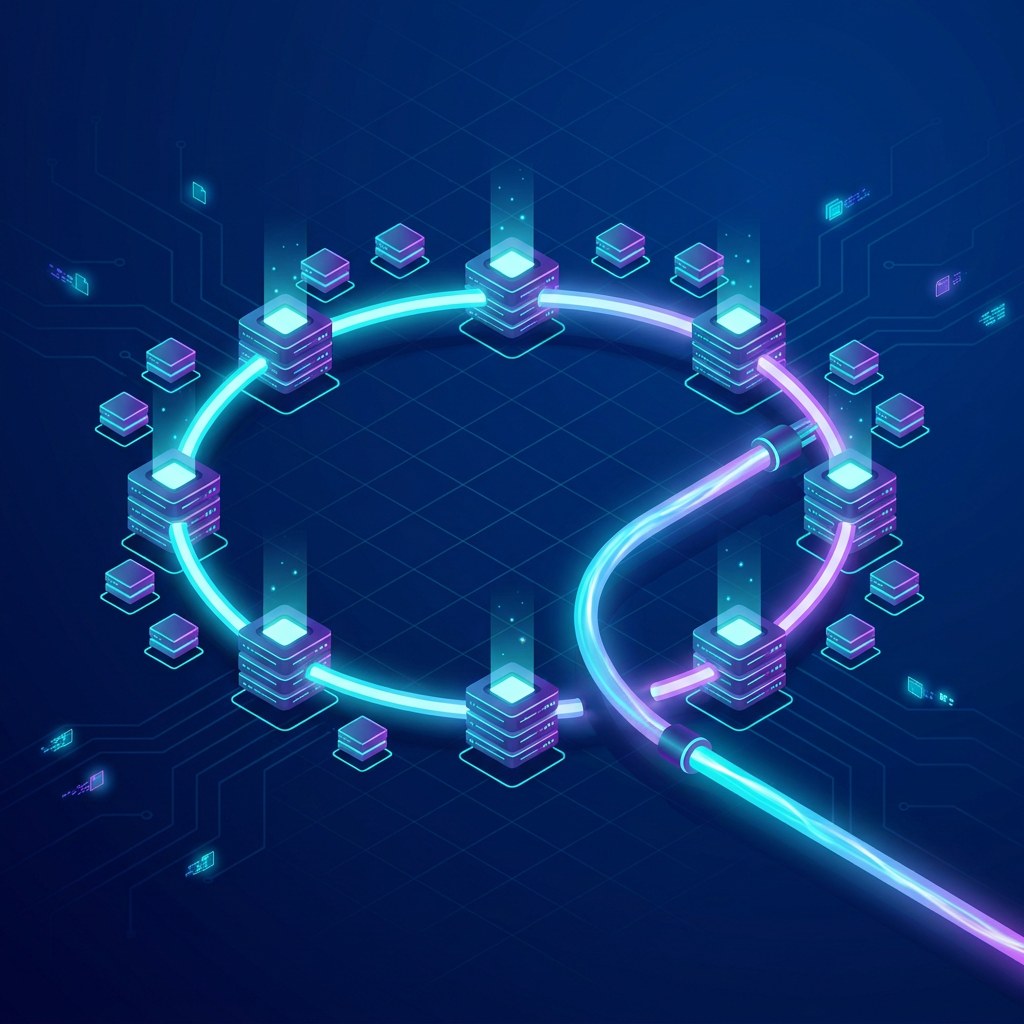
Consistent hashing changes the approach. Instead of computing a remainder, nodes are laid out over a circular hash space: a ring that wraps the full range of values the hash function can return (say, from 0 to 2³²−1).
Each node sits at a point on the ring computed from its own hash. Each key also has a position. The rule is then simple: a key belongs to the first node you find moving clockwise from the key’s point. This scheme needs no complex arithmetic: with an ordered structure (a balanced tree or sorted map) the successor is found in O(log N), and with a hash table over the ring’s points even in O(1).
Why it takes the blow
The key is that responsibilities are distributed by arcs (slices of the ring), not by a global division. When a node disappears, only the keys in its arc pass to the next node; everything else stays exactly where it was. When a new node joins, it only takes over its successor’s arc.
The result is an elegant mathematical property: the fraction of keys moved is, on average, on the order of 1/N. With ten nodes only 10 % of the keys get relocated on each change; with a hundred, 1 %. Shortcomings stay where they hurt the least.
The wrinkle: uneven node rows and virtual nodes
The basic scheme has a weakness: nodes fall onto random positions on the ring. By pure chance, some land close together while others leave enormous arcs, so one node can end up with a load far higher than its neighbours: the ring becomes unbalanced.
The standard solution is virtual nodes (or vNodes): each physical server is represented not by one point but by many replicas spread across the ring (say, 150 points per server). Because each one has points everywhere, the arcs end up similar in size and the load balances out. The classic memcached implementation, libketama, generated those points by computing an MD5("host-port-index") for every replica.
Where it actually lives
This is not a laboratory idea. It was proposed by Karger et al. in 1997 in the paper Consistent Hashing and Random Trees, and it has been embedded in well-known systems ever since: memcached (via libketama), Cassandra and DynamoDB (virtual nodes), Riak, and the load balancers that routed Akamai, the original content delivery network. It also sits behind the shards of many distributed databases.
An honest look at the limits
Consistent hashing minimizes the movement of keys but does not eliminate it: if the data is persistent, when an arc changes you still have to migrate the orphaned keys to the new owner, even if it is a small fraction. Nor does it solve hot keys: if one particular key concentrates enormous popularity, its node saturates all the same, because hashing knows nothing about access frequency. That requires replicating popular items across several nodes, an extra layer.
Still, fixing the split so that a failing node does not empty the whole cache at once is probably the difference between a harmless traffic spike and a cascading outage. A well-spread ring is, literally, what keeps part of the cache cold while the rest heats up all at once.