
A request to a modern API is rarely answered by a single program. It enters through a load balancer, passes an authentication gateway, calls three or four microservices, each one queries its own database, and one of them waits for an external service to respond. Even when every single one replies in 50 milliseconds, the original call takes 300. Someone is eating those milliseconds, and guessing who without tapping the conversation is nearly impossible.
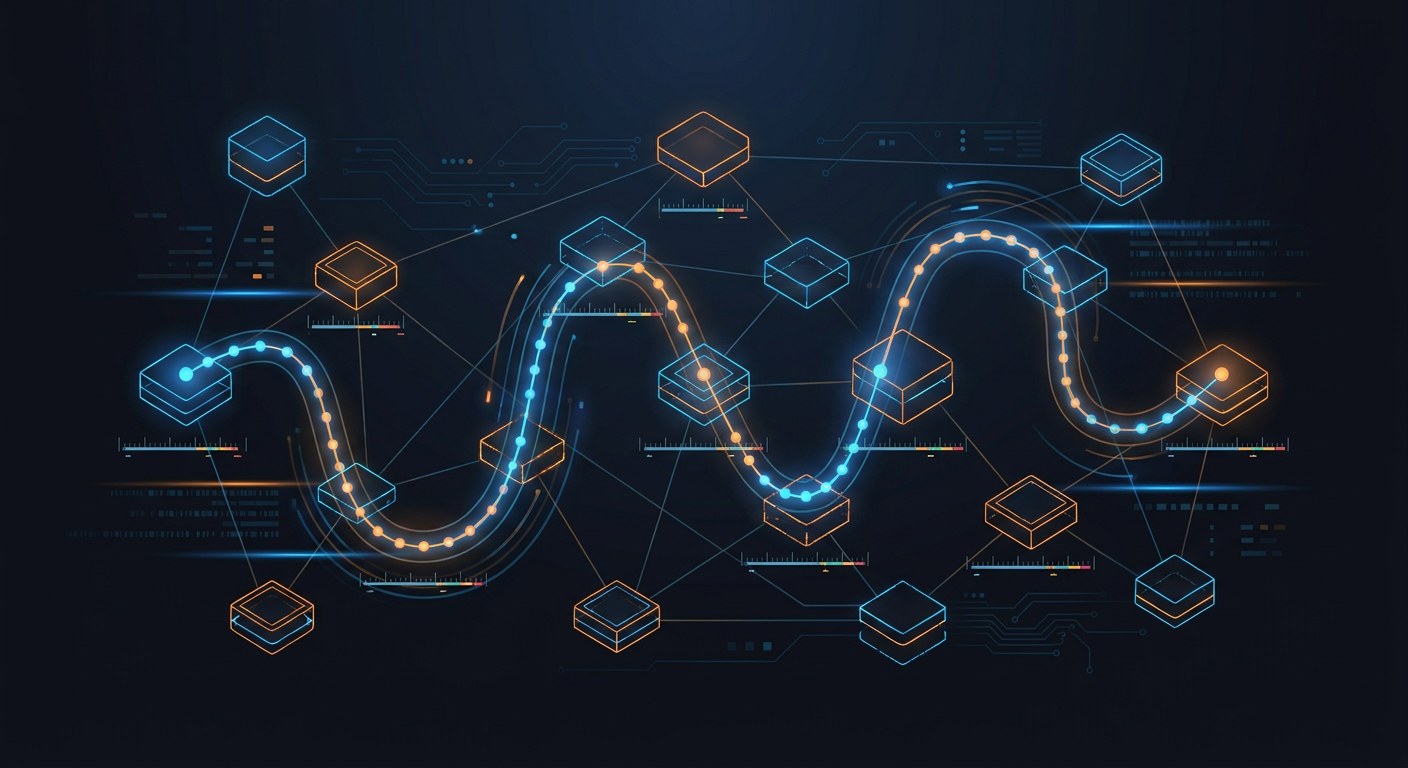
That tap is exactly what distributed tracing does: it rebuilds, request by request, the complete path a piece of data follows across every service it touches. It does not record “service A took 50 ms and B took 40 ms” as isolated numbers; it chains them into a single story with an order and a cause. For that it uses two key pieces worth understanding separately: spans and the trace.
A span is the smallest unit: an interval with a start, an end, a duration and a name describing what was being done — “get_user”, “query_mysql”, “call_payment_gateway”. When one service calls another, the caller’s span becomes the parent span and the span created by the called service is its child. All spans born from the same original request share one unique identifier, the trace_id, and together draw a tree. The result is visualized as a waterfall of horizontal bars: at the top the parent span spanning the whole duration, and below it its children in parallel or sequence. That is where you instantly see where the time piled up.
The trick is how that relationship travels between services. When a microservice responds it cannot “remember” for the next one which request it belonged to: each service in the cluster is an independent process on a different machine. The solution is to propagate context: each outgoing HTTP request carries, in its header, the trace_id and the current span id. The open standard for this is the W3C traceparent header, a single line holding the trace_id (sixteen bytes in hexadecimal), the parent span id and a sampling flag. Whoever receives the request reads that header, creates their own span as a child of the one indicated, and writes it back on the next call. That is how the tree is built hop by hop, with no component needing to know the full system topology.
Older systems used proprietary variants such as Zipkin’s X-B3-TraceId header or Jaeger’s; the OpenTelemetry standard consolidated them all into a single convention and also defines the API and SDK that instrument your code without tying you to a specific vendor. You keep writing your logic normally; the middleware injects and extracts the context automatically on every HTTP, database or message-queue call.
And here arises the biggest practical problem: volume. If you handle thousands of requests per second and store a trace for every one, you are duplicating your logging storage per request. The answer is sampling: only a percentage of complete traces are persisted, say 10% of requests. What is interesting is that sampling can be head-based (decided at the start, when the request arrives: that trace is recorded whole or not at all) or tail-based (decided at the end, keeping recent traces in memory to decide which ones deserve to be stored). The latter is more expensive but lets you keep only slow or erroring traces — precisely the ones worth investigating.
A non-trivial detail is that the sampling decision must be made exactly once. If each service decides on its own whether to record its span, you get traces with holes: the parent recorded, the middle one skipped, the last one recorded, so the waterfall is missing pieces and the diagnosis is crippled. That is why tracing first, and the sample/no-sample decision, happens at the entry point and propagates as part of the context.
The cheaper yet more limited alternative is the correlation ID (or request ID): any middleware generates a random id, adds it to the header, and every service includes it in its logs. It lets you stitch together the records of one request with a grep, but it gives you neither timings nor hierarchy: you do not know which span hung from which, or how long each step took. The correlation ID answers “what happened in this request?”, while tracing answers “where and how much time did this request lose?”.
Full observability is three legs, and they are worth keeping straight because they get confused: logs (discrete events, “this happened”), metrics (aggregated counters and averages, “how much and how often”) and traces (flow across services, “what happened before and after”). A good span also enriches its logs with attributes and baggage: data propagated with the context even when not every service reads it, handy for carrying a user id or tenant across the whole trace without stuffing them into every header.
The practical takeaway is: a distributed system is not debugged by instinct, it is debugged with context. When your API takes 300 milliseconds and every service swears it answered in 50, someone is lying — and only the trace, with its spans chained by propagated headers and its sampling well decided, tells you in which leg those 300 were lost.