
When several computers cooperate as a single system —a cluster— the biggest problem is neither speed nor storage: it is making all of them reach the same conclusion. If one node says the new value is 7 and another says it is 9, the whole system ends up in an unrecoverable state. Distributed consensus is the discipline that solves exactly that dilemma, and Raft is one of its most readable protocols.
The problem: clocks, outages, and lies
Imagine a replicated database across three machines, each holding its own copy. When a write arrives, all three must apply it identically, in the same order. The difficulty is not technical on a single node: it is coordinating several when there is no shared clock, when a machine can go down, when the network splits into two halves that cannot see each other, and when messages arrive out of order or duplicated.
The classic answer was Paxos, described by Leslie Lamport in the 1990s. It was correct but notoriously hard to understand and implement. Raft, presented in 2014 by Diego Ongaro and John Ousterhout, does not invent a new algorithm: it breaks the problem into small pieces a programmer can reason about one at a time.
Three roles, one leader
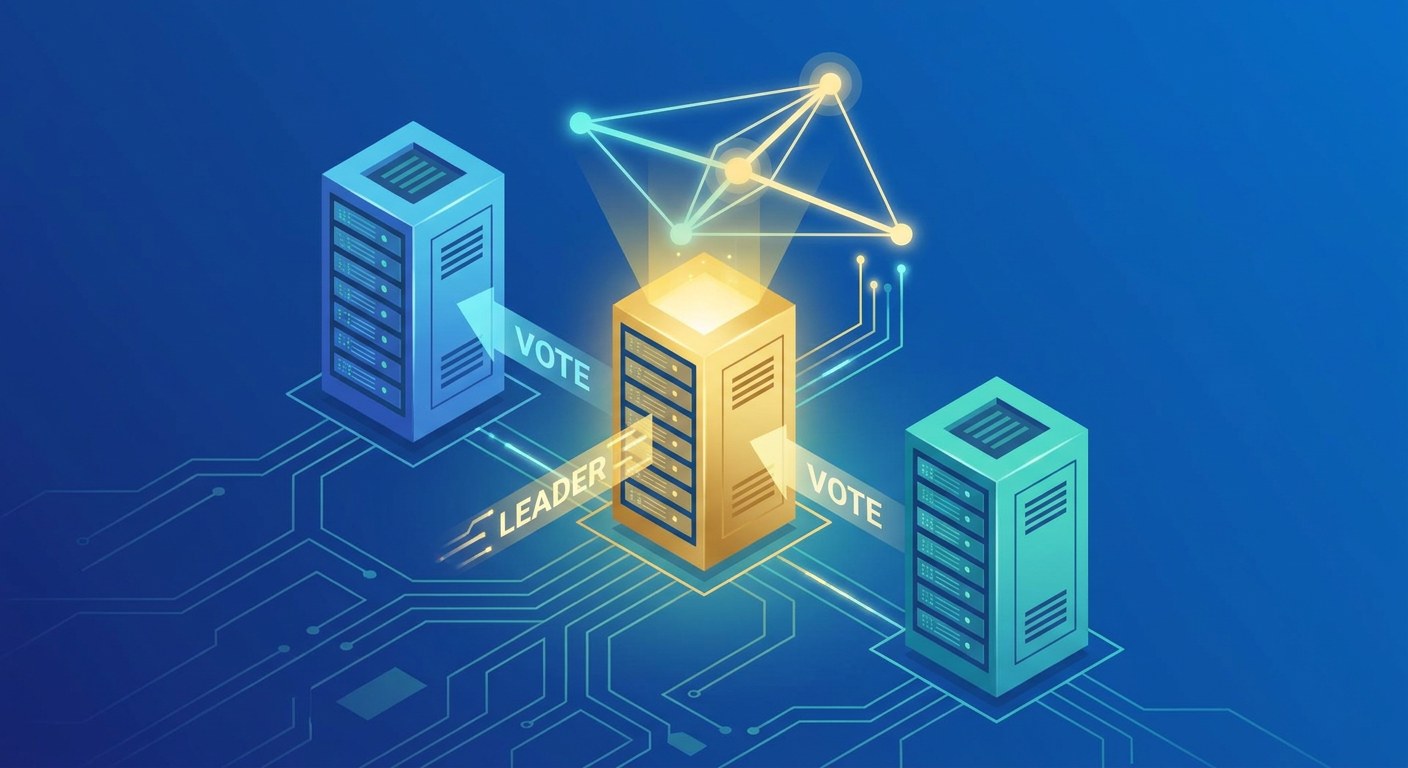
Raft puts every node into one of three states: leader, follower, or candidate. The trick to ordering writes is electing a single leader: all data flows through it, and followers just replicate what it dictates. Coherence is thus reduced to “the leader commands and the others copy”, much easier to reason about than a peer-to-peer network.
Time in Raft is divided into terms, numbers that increase with each election. Every term carries a sequence number, an idea borrowed directly from epoch numbers in other systems: it lets nodes know which messages are “from before” and which are “from now” even without synchronized clocks.
The election: votes and the election timeout
If a follower receives no signal from the leader during a random interval called the election timeout (typically 150–300 milliseconds), it infers the leader has failed and promotes itself to candidate: it increments its term, votes for itself, and asks the others for votes with a RequestVote message. Each node votes for only one candidate per term, so a majority (quorum, more than half the nodes) guarantees there is never more than one leader at a time.
The random interval is key: it prevents several nodes from jumping at once and fighting over the leadership. It relies on the same principle as backoff in networks: introducing entropy to break fatal synchrony.
The replicated log: the single source of truth
The central piece is the replicated log of entries. Each log entry holds the command (for example, “write X=7”) and the term number in which it was accepted. The leader accepts writes, appends them to its log, and sends them in parallel to followers using the AppendEntries message.
The majority rule applies again: when an entry is copied to more than half of the nodes, it is committed and can safely be applied to the state machine. Nodes that crashed and recovered rebuild their log by asking the leader for the missing part, since the leader keeps the complete log.
Safety: why it does not corrupt
Raft adds two invariants so the outcome is correct. The first, called Election Restriction: a candidate can only win if its log is at least as up to date as the others, comparing term and position of the last entry. This way nobody can arrive with an “outdated” log and destroy already-confirmed data.
The second, the Leader Completeness principle: any entry committed in a term will appear in the logs of all future leaders. Thanks to the majority, a new leader always finds already-confirmed entries and re-sends them, so what was agreed upon is never forgotten.
Configuration change and in practice
Changing the number of nodes in a cluster is delicate: if you add one at a time, there may be no quorum during the transition. Raft uses joint consensus: nodes briefly operate with both configurations at once, requiring majorities in both, until the change is confirmed.
Because of its readability, Raft appears in widely used real-world tools: etcd (Kubernetes’ configuration store), HashiCorp’s Consul, CockroachDB, TiKV, and the MongoDB replicator. It is the invisible engine that keeps a cluster from contradicting itself.
Conclusion
Raft shows that distributed consensus does not have to be hieroglyphics. With three roles, a replicated log, and the majority rule, a group of fallible machines manages to behave as one reliable one. The next time you store a value in a replicated system, behind the screen there is a leader chosen by votes and a log that everyone strives to keep identical.