
When you run an SQL query and the database answers in milliseconds, almost nobody stops to think that the heavy lifting is not done by the table: it is done by an auxiliary structure called an index. An index is to your data what a book’s index is to its pages: it does not hold the content, it holds the map to find it without reading everything.
The problem of a sequential search
Imagine a table with ten million rows. The most naive way to look up a value — the one a database uses when there is no index — is the full table scan: it reads all ten million rows one after another and compares each one against your filter. At best you settle for O(n), meaning the cost grows linearly with the size of the data. The price is pure disk access, and at ten million rows it starts to be felt.
Enter the B-tree
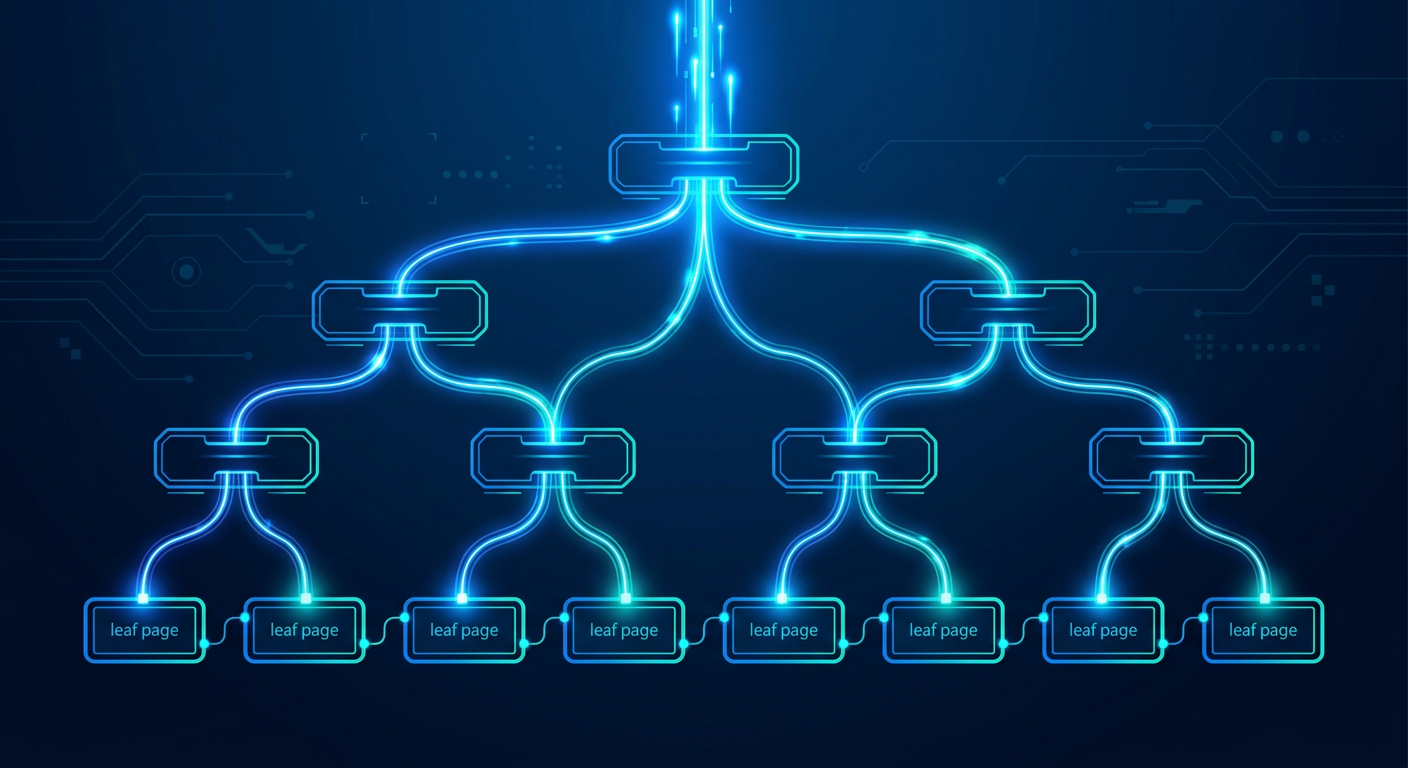
To avoid that scan, modern database engines (InnoDB in MySQL, the heap tables of PostgreSQL, SQL Server) organize their indexes as B-trees: balanced trees in which every node can have more than two children and all leaves end up at the same depth. The key idea is that the cost of a lookup drops from linear to O(log n): with ten million rows, fetching one record takes on the order of 20 or 30 comparisons, no matter what your query does.
Each tree node fits in a disk page (usually 8 or 16 KiB), so each step down a level costs exactly one disk read. That is why a B-tree with a high branching factor — hundreds of entries per page — can fit a million-row index in only three or four levels.
The data lives in the leaves
In the classic B-tree behind clustered indexes, the leaves also hold the complete rows or their pointers. In MySQL InnoDB the primary key IS the clustered index: the physical rows are stored ordered by it in the tree’s leaves, and the tree itself is the table. Every other index is a secondary index: its leaves hold the primary key value, not the whole row. When you query by a non-primary field, the planner makes two descents: first through the secondary index down to the primary key, and then through the clustered index to the row.
Why your query becomes a “covering index”
Out of this comes one of the most profitable performance tricks in modern SQL: if the index holds ALL the columns your SELECT needs, the database never returns to the table. That scenario is called a covering index and eliminates the second descent entirely. PostgreSQL, for instance, lets you attach extra columns with INCLUDE (from version 11) precisely so you can build covering indexes without bloating the key.
When the index gets in the way
The index is not free magic: it has to be maintained. Every INSERT, UPDATE or DELETE forces the engine to update all affected indexes, which slows down writes. That is why indexes only shine in workloads where reads clearly outnumber writes, and why you should not create an index on a whim: PostgreSQL’s EXPLAIN and MySQL’s EXPLAIN ANALYZE tell you whether the planner actually uses it or ignores it because the benefit does not pay off.
What if it does not fit in memory?
Key-value engines based on LSM-trees (RocksDB, Cassandra, LevelDB) chose the opposite path: structures optimized for writes, with an in-memory tree that keeps flushing into a series of sorted files (SSTables) compacted in the background. They are ideal for massive ingestion, though they pay for it with somewhat slower reads if you lack strong filter caching. The lesson is that there is no universal index: the right architecture depends on whether your system is read-heavy or write-heavy.
Next time a query takes milliseconds, remember that behind it there is a tree, a few dozen disk reads planned to the millimetre, and a stack of pages that the engine’s cache keeps hot in RAM.