
Every time you open a large app, you are not connecting to a single machine but to hundreds of servers sharing the load. For your session and your data to always appear where they belong, those machines rely on a technique called consistent hashing. It is one of the least known and most elegant ideas in systems engineering, and it explains why adding a server no longer throws your cache away.
The problem: where do I put this data
Picture a distributed cache: you have, say, ten servers and millions of key-value pairs to spread among them. The most naive way to decide which server holds each key is a modulo: you hash the key and compute hash(key) % 10 to get the server index. It is fast, but it has a brutal flaw: as soon as you grow to eleven servers, the operation becomes % 11 and practically every key changes places.
The result of that shift is a devastating phenomenon known as a cache stampede: all data migrates at once, the cache empties, and every request has to go back to the original database. Under load, that can take a service down in seconds. The same happens if a server dies: the modulo changes, everything relocates. Scaling should be a relief, not a fire.
The idea: put the servers on a ring
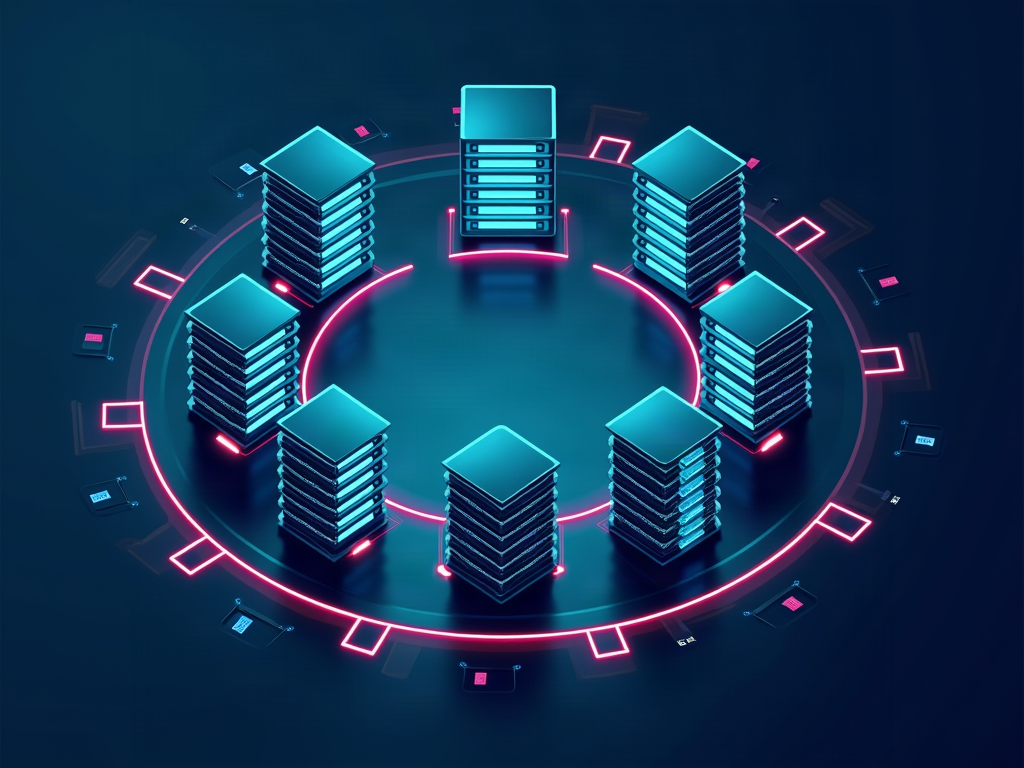
Consistent hashing changes the game. Instead of modulo arithmetic, it imagines a circle with 2³² possible positions, an address space from 0 to 4,294,967,295 called the hash ring. Both every server and every key are reduced to a point on that circle with the same hash function: the server at its address and the key at its own.
The placement rule is simple: a key belongs to the first server encountered when moving clockwise from the key’s point. So each server “owns” the arc of the ring that runs from its position back to the previous one. When a key arrives, it simply walks around the circle until it finds the server that claims it.
Why adding a node no longer hurts
Here is the magic. If you play with the ring with ten servers and add an eleventh at some random position, only the keys that fall into the arc that the new server “steals” from its neighbor are affected. Roughly 1/n of the keys move to the new machine; the rest stay exactly where they were. The same if a node dies: its keys are redistributed only among its two immediate neighbors, leaving the rest of the ring untouched.
This property — that only a fraction proportional to 1/n of the data changes on every rebalance — is what makes scaling or replacing a failure a cheap, almost invisible operation for the user. With classic modulo everything changed; here only a slice of the pie moves.
The trick of virtual nodes
The basic ring has a distribution problem: if servers land on very close points, some end up with huge arcs and others with almost nothing. To smooth it out, engineers use virtual nodes (“vnodes”): each real server is replicated as, say, 150 points scattered across the whole circle. When a key looks for a server, the winner is the nearest virtual node, and that node always knows which real machine it belongs to.
The effect is that load is spread far more evenly, almost in direct proportion to each machine’s capacity, because a server with more vnodes claims proportionally more arc and therefore more data. It is a way to balance weights without complicating the logic.
Where it really lives
This is not a lab idea: it is the backbone of modern infrastructure. It powers Redis Cluster and Cassandra for distributing data across nodes, advanced load balancers, caching systems such as Memcached in distributed mode, and a good share of content delivery networks (CDNs) when deciding which edge server answers each request. Amazon documented it formally in a famous 2007 paper attributed to its Dynamo team, and since then it has been copied into dozens of databases and message queues.
The next time an application’s infrastructure grows without you noticing, a hash ring — and a handful of virtual nodes — will have worked hard so that adding one more machine only moves the right slice of data, not all of it.